Darko Milosevic, Dr.rer.nat./Dr.oec.

Please fill free to lisen music until you read blog :-)
Showing posts with label Econometrics. Show all posts

Regression analysis

Regression analysis

( _Forma-Sadrzaj_DOPUNJEN - SMANJEN.doc)

When investigating the relationship between two variables regression analysis is an appropriate tool. In a regression analysis one variable needs to be distinguished as the dependent variable and the other as the independent variable. When a variable is named the dependent variable, it means that the values of this variable depend on the values of another variable. The independent variable explains the dependent variable. (Lee et al., 2000) For example, if we were to investigate the relationship between eyesight and age, the dependent variable would be eyesight and the independent variable would be age. The reason is that it is most likely that the older a person gets, the worse his or her eyesight gets, and a person’s age is therefore an explaining factor when it comes to that person’s eyesight. 
When only one variable is assumed to explain the value of another variable, meaning there is one dependent and one independent variable, it is called simple regression. However, if it is thought that more than one variable explains the value of the dependent variable, multiple regression analysis is used. In multiple regression analysis, the relationship between a dependent variable and more than one independent variable can be determined. 

Regression analysis provides two important results which are presented below. The most important result in this study is related to the marginal change in Y related to changes in the independent variables:
1)      An estimated linear equation that describes the dependent variable, Y, as a function of a number of K observed independent variables, xj, where j = 1,…,K,.
Y = b0 + b1x1i + b2x2i + … + bKxKi where i = 1,…,n observations.
2)      The marginal change in the dependent variable, Y, related to changes in independent variables represented by bj’s. The coefficient bj indicates the change in Y given a unit change in xj while controlling for the simultaneous effect of other independent variables. (Newbold et al., 2007)
When applying multiple linear regression, a model is constructed to explain variability in the dependent variable chosen. The multiple regression model is:
yi = β0 + β1x1i + β2x2i + … + βKxKi + εi   

where 
      εi  is the random error term
   βj  are coefficients of marginal effects of the independent variables
  xj  are the independent variables selected, also known as explanatory variables
    j  indicates the index of the specific independent variable, j = 1,…,K
    i  indicates the specific observation, I = 1,…,n (Newbold et al., 2007)

In multiple regression analysis the ordinary least‐square method is used to estimate the regression parameters. The least square method is based on the idea that the sum of the squared deviations is to be minimized.  With deviation, the distance from the constructed plane to the actual observation is referred to. In other words the least square method aims to minimize the errors when constructing the regression plane from where the intercept and the regression coefficients are found. Below, this is formulated in mathematical terms for a case when there is one dependent variable and two independent variables: (Lee et al., 2000)

             Minimize ∑             ∑                                           
This method can only be illustrated graphically in two and three dimensions; however in regression analysis more than two independent variables can be used to determine the relationship between a dependent variable and these independent variables. 
Regression plane with Y as dependent variable and X1 and X2 as independent variables. The regression plane is created to minimize the deviation (residuals) in the observations. (www.sjsu.edu, 2007‐11‐20)
In such a model where the intercept, β0, and the regression coefficients, β1,…, βK, are assumed to be constant and there is residual homogeneity and normality, the model can be estimated with ordinary least square estimation (Yaffee, 2007‐11‐20). 

When the data used in a regression analysis includes multiple cases (companies, people, countries etc.) that are observed at two or more time periods it is called panel data. The use of panel data complicates the ordering of the data and the calculation process since there is an extra dimension, apart from studying several companies they are also studied over time. Therefore this type of data is commonly simplified into what is called pooled data. Pooled data means that all data is merged into one dimension. This implies that the panel data characteristics are disregarded, however in the case where the intercept and the regression coefficients are assumed to be constant over time it is recommended to proceed in this way. Further, panel data can appear balanced or unbalanced. Balanced panel data means that the numbers of time series observations are equal in each crosssection, whereas unbalanced data means that the numbers of time series observations are not equal in each cross section. (Antell, 2007‐10‐22 and Yaffee, 2007‐11‐20).

Before performing a regression analysis hypothesis regarding the relationship between the dependent and independent variables are formulated. After performing the regression analysis it can then be concluded, in the case of significant results, that the relationship between the variables is of a certain type.

There are two special types of variables that can be used as independent variables. These variables are called dummy variable and interaction variable. A dummy variable is a type of variable that take only two values, 0 or 1, and it can be a powerful tool in multiple regression, especially when in situations involving categorical variables. For example a dummy variable could indicate if a person smokes or not by taking on the value 1 in those cases when a person smokes and 0 if the person does not smoke. It is a simple way to symbolize different categories. An interaction variable is the product of two variables. It investigates whether the combination of two variables is extra strong. For example, it might be relevant to include an interaction variable if investigating the growth of crops. Using a fertilizer might imply that the crops grow particularly well, also rain fall might be a factor that influences the growth of the crop. In this case it would be a good idea to include an interaction variable to investigate what happens in the case when fertilizer is used and there is rain fall. (Newbold et al., 2007).

To find the level of significance of the results of regression analysis, several methods can be used. One of these methods is the t‐test, where a calculated t‐value is translated into a p‐value which shows the level of significance. There are two types of t‐tests, one‐tailed and two‐tailed. The onetailed t‐test is used if the results are interesting only if they turn out in a particular direction. The two‐tailed t‐test is performed if the results are interesting despite direction.

Illustration of one‐tailed t‐test and two‐tailed t‐test.

Calculations necessary to perform multiple regression can be executed by computer programs such as Excel, SPSS, STATA, Minitab and SAS. In this thesis work, the statistical package STATA was used. The sign of the calculated regression coefficients, βi:s, can be interpreted as showing whether the dependent and independent variables are positively or negatively related. The t‐statistics calculated in regression analysis are used to determine the significance of the results. STATA produces p‐values based on two‐tailed t‐tests. To get the correct p‐values in this study where a one‐tailed t‐test is wanted, the p‐value provided by STATA is divided by two.  

Summer School Unical | Structural equation models | Panel models

Još jedna stvar, Felice je pohađao letnju školu Summer School Unical - Microeconomics using STATA, gde iz slika mogu da vidim da su radili jednačine iz ekonometrije i koristili program gretl.

Structural equation models (Modelli di equazioni strutturali)
Teachers: Gaetano Nino Miceli, Maria Antonietta Raimondo - Universita della Calabria

Basic elements on the linear regression model and factor analysis (eg., schools econometric analysis - Basic course, Multivariate Analysis for Social Research)

Content and course programs:
- Causal Analysis and Measurement
- The development of scales of measurement
- Analysis of reliability and validity
- Confirmatory Factor Analysis of the first order and second-order models
- Models of structural equations and path analysis
- Applications with SPSS and Lisrel 8.80

Panel models (Modelli panel)
Teachers: Randolph L. Bruno (University College London)
Fabiola Montalto (University of Calabria)

Input Required skills: basic elements on the linear regression model (eg., school econometric analysis - Basic Course)

Content and course programs:
- The multiple regression analysis with longitudinal data
- Compare cross sections data and panel data
- Balanced and unbalanced panel Models: data organization
- Estimator fixed effects, estimator "between" estimator and random effects
- Reconciling fixed effects and random effects
- Panel with discrete dependent variables
- Dynamic Panel
- Replicate analyzes of a paper published
- Applications with STATA


Preporuka da vise o ovome citam:
https://www.google.rs/webhp?sourceid=chrome-instant&ion=1&espv=2&ie=UTF-8#q=Microeconomics+using+STATA+Structural+equation+models


Granger causality method

Granger causality

From Wikipedia, the free encyclopedia
When time Series X Granger causes time series Y, the patterns in X are approximately repeated in Y after some time lag (two examples are indicated with arrows). Thus, past values of X can be used for the prediction of future values ofY.
The Granger causality test is a statistical hypothesis test for determining whether one time series is useful in forecasting another, first proposed in 1969.[1] Ordinarily,regressions reflect "mere" correlations, but Clive Granger argued that causality in economics could be tested for by measuring the ability to predict the future values of a time series using prior values of another time series. Since the question of "true causality" is deeply philosophical, and because of the post hoc ergo propter hoc fallacy of assuming that one thing preceding another can be used as a proof of causation, econometricians assert that the Granger test finds only "predictive causality".[2]
A time series X is said to Granger-cause Y if it can be shown, usually through a series of t-tests and F-tests on lagged values of X (and with lagged values of Y also included), that those X values provide statistically significant information about future values of Y.
Granger also stressed that some studies using "Granger causality" testing in areas outside economics reached "ridiculous" conclusions. "Of course, many ridiculous papers appeared", he said in his Nobel Lecture, December 8, 2003.[3] However, it remains a popular method for causality analysis in time series due to its computational simplicity.[4][5] The original definition of Granger causality does not account for latent confounding effects and does not capture instantaneous and non-linear causal relationships, though several extensions have been proposed to address these issues.[4]

Intuition[edit]

We say that a variable X that evolves over time Granger causes another evolving variable Y if predictions of the value of Y based on its own past values and on the past values of X are better than predictions of Y based only on its own past values.

Underlying principles[edit]

Granger defined the causality relationship based on two principles:[4][6]
  1. The cause happens prior to its effect.
  2. The cause has unique information about the future values of its effect.
Given these two assumptions about causality, Granger proposed to test the following hypothesis for identification of a causal effect of X on Y:

\mathbb{P}[Y(t+1) \in A|\mathcal{I}(t)] \neq \mathbb{P}[Y(t+1) \in A|\mathcal{I}_{-X}(t)]
where \mathbb{P} refers to probability, A is an arbitrary non-empty set, and \mathcal{I}(t) and \mathcal{I}_{-X}(t) respectively denote the information available as of time t in the entire universe, and that in the modified universe in which X is excluded. If the above hypothesis is accepted, we say that X Granger causes Y.[4][6]
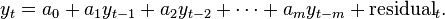
Method[edit]

If a time series is a stationary process, the test is performed using the level values of two (or more) variables. If the variables are non-stationary, then the test is done using first (or higher) differences. The number of lags to be included is usually chosen using an information criterion, such as the Akaike information criterion or the Schwarz information criterion. Any particular lagged value of one of the variables is retained in the regression if (1) it is significant according to a t-test, and (2) it and the other lagged values of the variable jointly add explanatory power to the model according to an F-test. Then the null hypothesis of no Granger causality is not rejected if and only if no lagged values of an explanatory variable have been retained in the regression.
In practice it may be found that neither variable Granger-causes the other, or that each of the two variables Granger-causes the other.

Mathematical statement[edit]

Let y and x be stationary time series. To test the null hypothesis that x does not Granger-cause y, one first finds the proper lagged values of y to include in a univariate autoregression of y:
y_t = a_0 + a_1y_{t-1} + a_2y_{t-2} + \cdots + a_my_{t-m} + \mathrm{residual}_t.
Next, the autoregression is augmented by including lagged values of x:
y_t = a_0 + a_1y_{t-1} + a_2y_{t-2} + \cdots + a_my_{t-m} + b_px_{t-p} + \cdots + b_qx_{t-q} + \mathrm{residual}_t.
One retains in this regression all lagged values of x that are individually significant according to their t-statistics, provided that collectively they add explanatory power to the regression according to an F-test (whose null hypothesis is no explanatory power jointly added by the x's). In the notation of the above augmented regression, p is the shortest, and q is the longest, lag length for which the lagged value of x is significant.
The null hypothesis that x does not Granger-cause y is not rejected if and only if no lagged values of x are retained in the regression.

Multivariate analysis[edit]

Multivariate Granger causality analysis is usually performed by fitting a vector autoregressive model (VAR) to the time series. In particular, let X(t) \in \mathbb{R}^{d\times 1} for t=1, \ldots, T be a d-dimensional multivariate time series. Granger causality is performed by fitting a VAR model with L time lags as follows:

X(t) = \sum_{\tau=1}^{L}A_{\tau}X(t-\tau) + \varepsilon(t),
where \varepsilon(t) is a white Gaussian random vector. A time series X_i is called a Granger cause of another time series X_j, if at least one of the elements A_{\tau}(j, i) for \tau = 1, \ldots, L is significantly larger than zero (in absolute value).[7]

Limitations[edit]

As its name implies, Granger causality is not necessarily true causality. If both X and Y are driven by a common third process with different lags, one might still fail to reject the alternative hypothesis of Granger causality. Yet, manipulation of one of the variables would not change the other. Indeed, the Granger test is designed to handle pairs of variables, and may produce misleading results when the true relationship involves three or more variables. A similar test involving more variables can be applied with vector autoregression.

Extensions[edit]

A method for Granger causality has been developed that is not sensitive to deviations from the assumption that the error term is normally distributed.[8] This method is especially useful in financial economics since many financial variables are non-normally distributed.[9] Recently, asymmetric causality testing has been suggested in the literature in order to separate the causal impact of positive changes from the negative ones.[10]

Granger causality in neuroscience[edit]

A long held belief about neural function maintained that different areas of the brain were task specific; that the structural connectivity local to a certain area somehow dictated the function of that piece. Collecting work that has been performed over many years, there has been a move to a different, network-centric approach to describing information flow in the brain. Explanation of function is beginning to include the concept of networks existing at different levels and throughout different locations in the brain.[11] The behavior of these networks can be described by non-deterministic processes that are evolving through time. That is to say that given the same input stimulus, you will not get the same output from the network. The dynamics of these networks are governed by probabilities so we treat them as stochastic (random) processes so that we can capture these kinds of dynamics between different areas of the brain.
Different methods of obtaining some measure of information flow from the firing activities of a neuron and its surrounding ensemble have been explored in the past, but they are limited in the kinds of conclusions that can be drawn and provide little insight into the directional flow of information, its effect size, and how it can change with time.[12] Recently Granger causality has been applied to address some of these issues with great success.[13] Put plainly, one examines how to best predict the future of a neuron: using either the entire ensemble or the entire ensemble except a certain target neuron. If the prediction is made worse by excluding the target neuron, then we say it has a “g-causal” relationship with the current neuron.

Extensions to point process models[edit]

Previous Granger-causality methods could only operate on continuous-valued data so the analysis of neural spike train recordings involved transformations that ultimately altered the stochastic properties of the data, indirectly altering the validity of the conclusions that could be drawn from it. Recently however, a new general-purpose Granger-causality framework was proposed that could directly operate on any modality, including neural-spike trains.[12]
Neural spike train data can be modeled as a point-process. A temporal point process is a stochastic time-series of binary events that occurs in continuous time. It can only take on two values at each point in time, indicating whether or not an event has actually occurred. This type of binary-valued representation of information suits the activity of neural populations because a single neuron’s action potential has a typical waveform. In this way, what carries the actual information being output from a neuron is the occurrence of a “spike”, as well as the time between successive spikes. Using this approach one could abstract the flow of information in a neural-network to be simply the spiking times for each neuron through an observation period. A point-process can be represented either by the timing of the spikes themselves, the waiting times between spikes, using a counting process, or, if time is discretized enough to ensure that in each window only one event has the possibility of occurring, that is to say one time bin can only contain one event, as a set of 1s and 0s, very similar to binary.
One of the simplest types of neural-spiking models is the Poisson process. This however, is limited in that it is memory-less. It does not account for any spiking history when calculating the current probability of firing. Neurons, however, exhibit a fundamental (biophysical) history dependence by way of its relative and absolute refractory periods. To address this, a conditional intensity function is used to represent the probability of a neuron spiking,conditioned on its own history. The conditional intensity function expresses the instantaneous firing probability and implicitly defines a complete probability model for the point process. It defines a probability per unit time. So if this unit time is taken small enough to ensure that only one spike could occur in that time window, then our conditional intensity function completely specifies the probability that a given neuron will fire in a certain time.

See instead[edit]

 
CONTACT FORM
Please fill contact form in details:
Name and surname:  *
E-mail:  *
Telephone:  *
Arrival:  *
Check out:  *
Number of Persons:  *
Accommodation Type:
Price:
Destination:  *
Business Sector:
Subject:  *
Wishes and comments:
 
 
 *Must be filled with fields.